Use animation when your explainer is built on charts, diagrams, text and data that must stay precisely editable; use AI-generated footage when you need realistic scenes, people or product shots. Most strong faceless explainers combine both, and the decision should be made per scene, not per channel.
Key takeaways:
- Anthropic launched Claude Motion in beta for Team and Enterprise plans on October 8, 2026, creating animations from text, charts, shapes and images and exporting MP4 files.
- Anthropic states Claude Motion writes animation code rather than using a video-generation model, and it does not generate realistic footage or people.
- Claude Motion's documentation describes changing individual words, numbers or timing while leaving the rest of an animation intact, but provides no end-to-end time-saving or per-video cost benchmark.
- Runway's product-video guide documents a script-to-approved-keyframes-to-animation workflow, giving generated footage a concrete approval structure.
- Neither route has documented evidence proving it is always faster or cheaper; the honest comparison is about fit, not speed.
| Criterion | Code-based animation | AI-generated footage |
|---|---|---|
| Visual purpose | Diagrams, charts, text-led explanation, data callouts | Realistic scenes, people, products, atmosphere |
| Realistic depictions | No: Anthropic says Claude Motion does not generate realistic footage or people | Yes: built for photoreal or stylized realism |
| Targeted revisions | Change one word, number or timing value, rest stays intact | Usually regenerate the shot; surrounding pixels change too |
| Export and approval workflow | Edit code/parameters, export MP4 (Claude Motion beta, Oct 8, 2026) | Script, generate and approve keyframes, then animate (Runway guide) |
| Best-fit explainer scenes | Metrics, processes, comparisons, step-by-step logic | B-roll, context shots, human presence, physical products |
Which should you choose? If your video explains numbers, systems or concepts, default to animation and add generated footage only where realism earns its place. If your video sells a physical product, shows a setting, or needs a human figure, default to generated footage with a keyframe approval step. If you publish a mixed format, such as a business explainer with data sections and contextual b-roll, plan for both from the script stage.
What is the difference between code-based animation and generated footage?
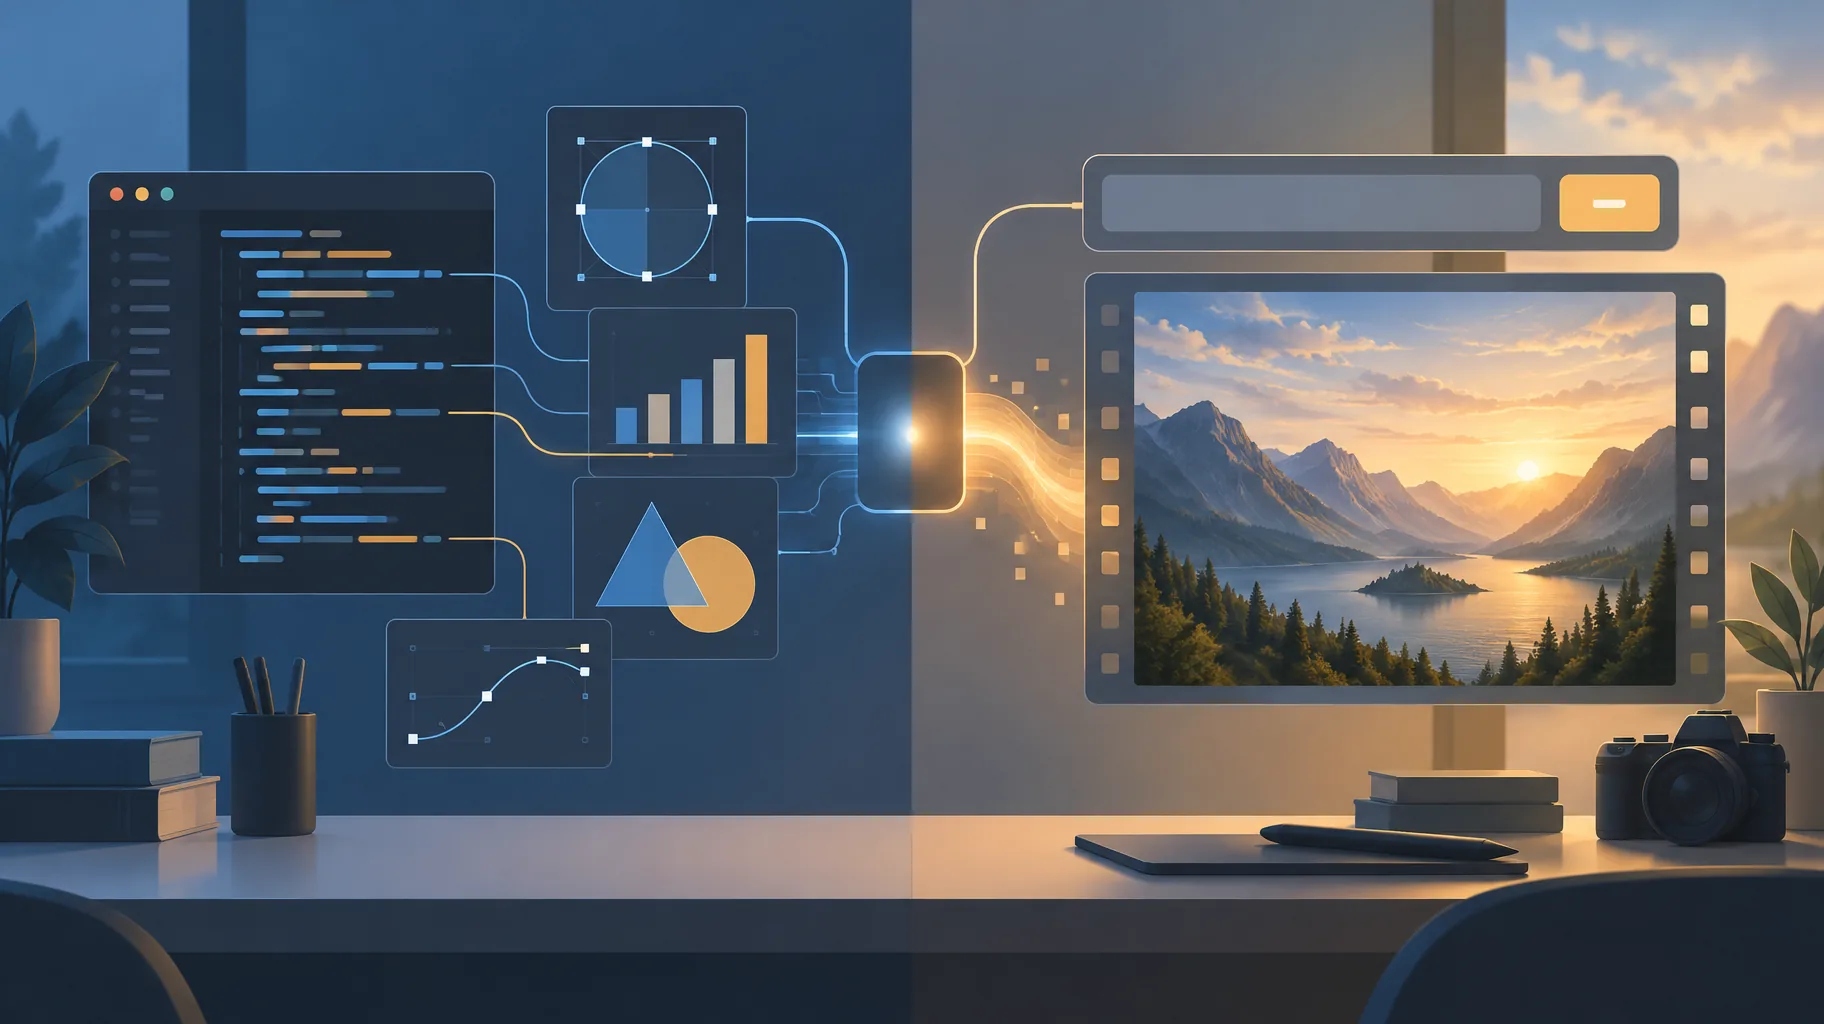
Code-based animation is built from instructions: the tool writes animation code that places text, charts, shapes and images on a timeline, then renders that code to a video file. Generated footage is produced by a video-generation model that predicts pixels directly from a prompt, creating imagery that can look photographic. The practical difference is control: code-based animation gives you addressable objects you can edit by name, while generated footage gives you realism at the cost of precision.
Anthropic's October 8, 2026 launch of Claude Motion in beta for Team and Enterprise plans is the clearest recent evidence of the editable-animation category. Anthropic says Claude Motion writes animation code rather than using a video-generation model, and the same announcement confirms it builds animations from text, charts, shapes and images and exports them as MP4 files. That is a different technical path from a video model, and it explains both the strengths (exact values, clean diagrams) and the limits (no realistic people or scenes).
Generated footage sits at the other end. A video model can produce a convincing office, a hand holding a product, or a sweeping landscape, but the output is a finished frame of pixels. You steer it with prompts and reference images, not by editing a labeled object. Both routes end in an MP4; what differs is how much you can change after the first render.
Which approach fits charts, diagrams and text-led explanations?
Code-based animation fits charts, diagrams and text-led explanations, because every element is a defined object with exact values, positions and timing. A bar labeled 47 percent stays 47 percent through every revision, and a step diagram keeps its alignment when you swap one label. Generated footage struggles here: asking a video model for an accurate chart often produces plausible-looking but wrong numbers and garbled text.
This is the use case Claude Motion was built for. Its launch announcement describes animations built from text, charts, shapes and images, which maps directly onto the visual vocabulary of educational and business explainers. If your channel explains revenue models, study results or workflows, animation should be your default layer.
Creators weighing this choice against other visual sources will find a related breakdown in our comparison of stock footage and AI visuals for faceless videos, which covers the b-roll side of the same decision.
Which approach can create realistic scenes or people?
AI-generated footage is the only one of the two that can create realistic scenes or people. Anthropic is explicit that Claude Motion does not generate realistic footage or people, because it writes animation code instead of running a video-generation model. If your explainer needs a viewer to believe they are looking at a real place, product or person, generated footage is the appropriate tool.
That capability carries a compliance note. YouTube's altered-or-synthetic-content disclosure, introduced March 18, 2024, applies to realistic depictions viewers could mistake for real people, places, scenes or events, not to clearly unrealistic animation or production assistance like scripts and captions. So a realistic generated scene may need disclosure while an animated diagram does not. Our guide to AI content disclosure rules for video creators walks through how to judge each case. The rule turns on what the video depicts, not on whether your channel shows a face.
Can I change one word or number without changing the whole animation?
Yes, with code-based animation. Claude Motion's help documentation describes changing individual words, numbers or timing while leaving the rest of an animation intact. Because the animation is code, a revision edits a parameter rather than re-rendering a scene from scratch, so the chart you approved last week survives this week's correction to one figure.
With generated footage, the honest answer is usually no. A wrong digit burned into a generated shot means regenerating, and the new generation may shift lighting, framing or style along with the fix. For data-focused creators who publish corrections or update statistics regularly, this difference alone can decide the format. One caution: the same documentation provides no end-to-end time-saving or per-video cost benchmark, so treat targeted revision as a documented capability, not a proven savings figure.
Where should keyframe approval fit into a generated-footage workflow?
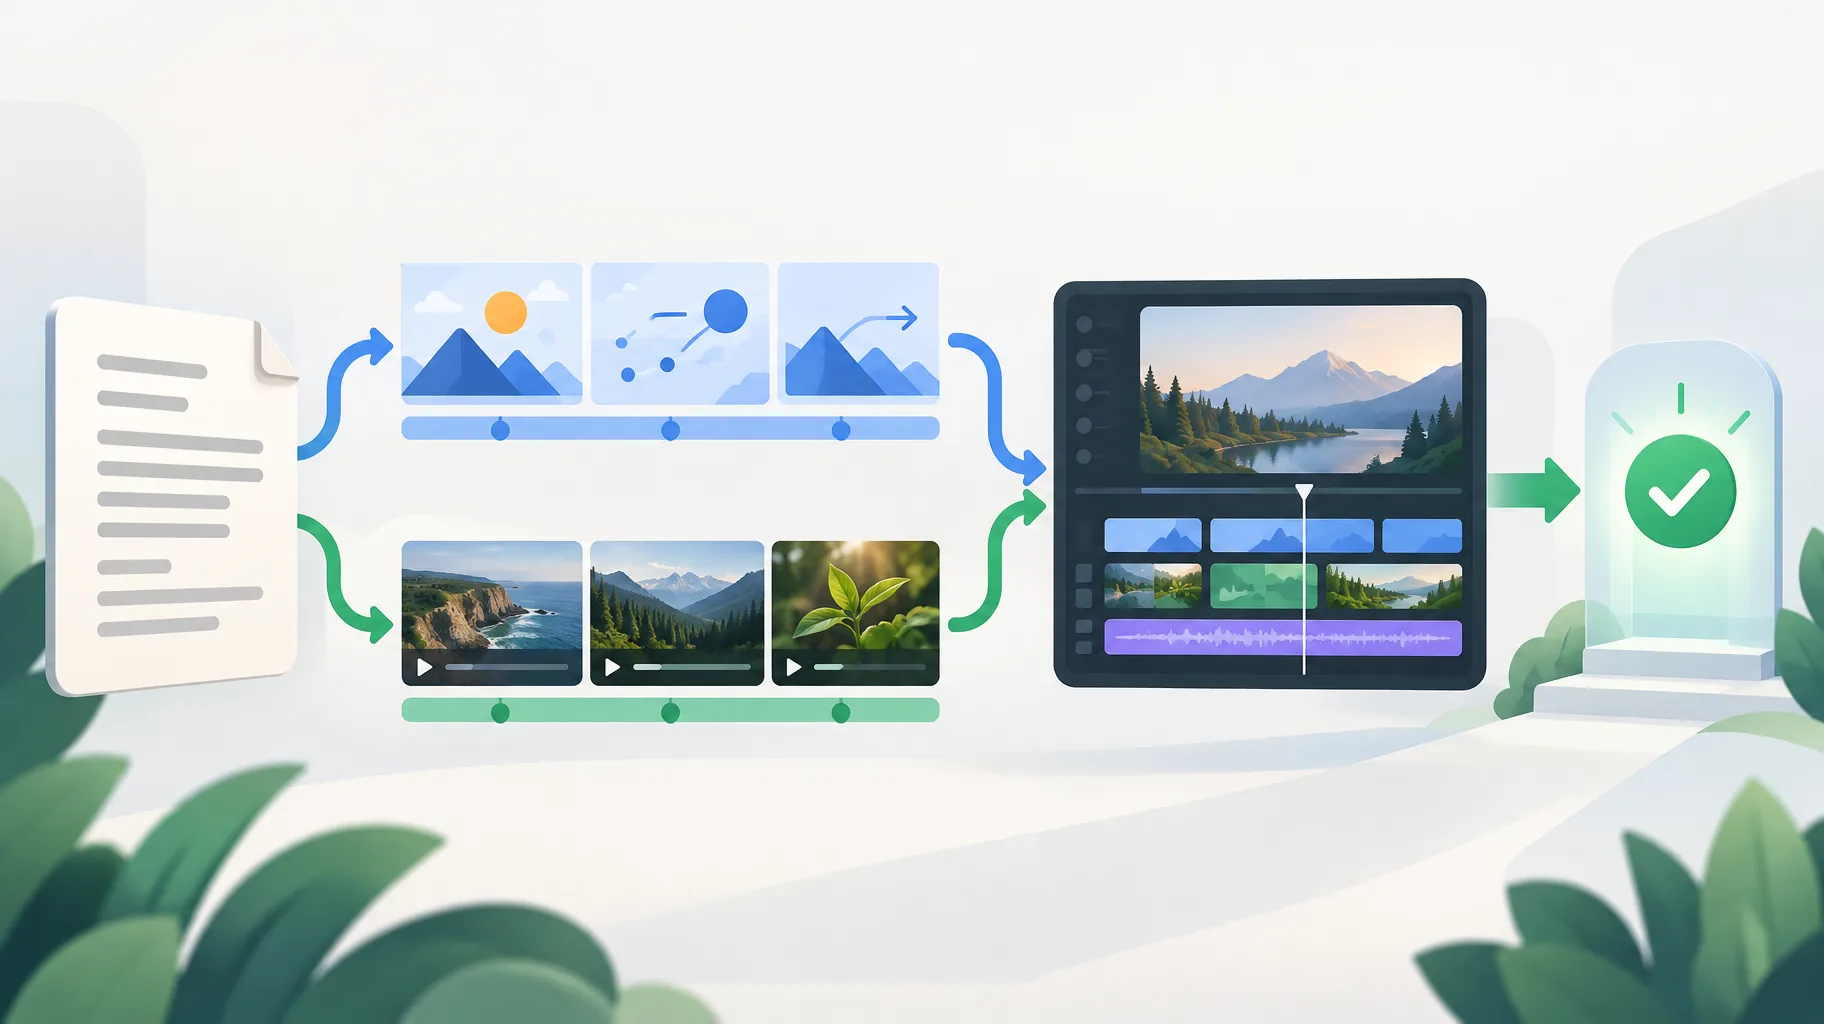
Keyframe approval should sit between scripting and full animation, as a hard gate. Runway's product-video guide documents exactly this sequence: write the script, generate and approve keyframes for each shot, then animate the approved keyframes into motion. Approving stills first is far cheaper than rejecting finished clips, because a keyframe commits you to composition, subject and style before motion is generated.
A practical generated-footage workflow looks like this:
- Script first: lock narration and shot list before generating anything.
- Generate keyframes: produce still candidates for each shot.
- Approve the gate: a human signs off on every keyframe; rejected shots loop back here, not after animation.
- Animate approved keyframes only: motion budget goes to shots that already passed review.
- Assemble and review: cut clips against the voiceover, then do one final pass.
This structure matters more than the tool. Rejected generations are a real cost in any footage workflow, and an approval gate is how you keep that cost visible instead of discovering it at the render step.
Does animation automatically cost less than generated video?
No. There is no documented evidence that animation automatically costs less than generated footage, or the reverse. Claude Motion's documentation describes its revision capabilities but provides no per-video cost benchmark, and no supplied evidence establishes a universal production-time figure for either route. Any article claiming one side is always cheaper is asserting something the available data does not support.
What you can compare honestly is where costs hide. Generated footage budgets are consumed by rejected generations and regeneration cycles, which the keyframe gate above is designed to contain. Animation budgets concentrate in up-front iteration on the code and design, then revisions get cheap. Your real cost driver is how many revision rounds your content needs: a statistics channel updating numbers weekly will feel the difference differently than a storytelling channel that rarely revises. For a fuller budget picture, see our practical guide to AI video production costs, and for time expectations, our breakdown of how long a faceless YouTube video takes.
Can I combine animation and generated footage in one explainer?
Yes, and for most educational and business explainers you should. A common pattern: animated charts and diagrams carry the argument, generated footage provides context shots and transitions, and captions plus voiceover hold it together. Both routes export standard video files, so mixing them is an assembly problem, not a compatibility problem.
The assembly layer is where an AI faceless-video platform can help, provided it accepts the assets you produce. GoFaceless (our own product) is one option here: it turns a topic or brief into a finished short-form video with script, voiceover, visuals, captions and music in one pass, with preview and export controls, targeting TikTok, Reels and Shorts in vertical and 16:9. It suits creators who want the pipeline handled end to end; creators who need frame-level control over custom animation code will still want a dedicated animation tool upstream. Either way, keep one editorial checkpoint in the process. As TeamYouTube put it when clarifying the platform's inauthentic content policy, "These guidelines apply regardless of how the content was made." A reusable mixed-media template is fine; interchangeable substance is not.
Putting the decision into practice
Pick your default layer by content type: animation for data and logic, generated footage for realism, both for anything in between. If you want a fast way to test the mixed approach, GoFaceless assembles script, voiceover, visuals and captions into a finished short-form video in one pass, and pricing starts at $29 per month. Whichever tools you choose, decide per scene, keep an approval gate on generated shots, and let the idea dictate the visuals rather than the other way around.
Sources & further reading
Keep reading
How Long Should a Faceless TikTok Video Be for Creator Rewards?
TikTok Creator Rewards requires original videos over one minute. Learn the launch eligibility rules, the rewards formula, AI disclosure duties and how to verify your account.
The Growth of AI-Generated Shorts: What Creators Need to Know
Learn what the available 2026 AI Shorts data says about creator adoption, render time, originality, disclosure, and testing workflows.
How 3–7 Second Videos Perform for Engagement
Data-backed analysis of how 3–7 second videos perform on viewability, sharing, conversion, messaging, and algorithm signals.